
Platform reference: this article follows the Rockchip RKNN2 SDK V2.5.0 Development Guide, including only the SoCs, Linux/Android Runtime and Toolkit combinations stated by the source. Features apply under the chip, SDK, driver and kernel conditions in each section, not automatically to every ArmSoM board. Check the actual ArmSoM BSP, NPU driver, Runtime and model versions before deployment. No ArmSoM hardware validation was performed; logs, performance figures and examples belong to the source.
Sources and proofreading: Chinese follows Chinese V2.5.0 (182 pages); English, Russian and German follow English V2.5.0 (208 pages). Source-specific technical information is retained; older-version content is not presented as new-version fact. Chinese figures come from the Chinese PDF; EN/RU/DE figures come from the English PDF, including separately extracted vector flowcharts. Original section and equation numbers remain. Some source cross-references still use old chapter numbers; dynamic-shape capacity examples contain “1224+140=264”, TP_NORM support statements conflict, and names such as init()/rknn.val_perf() differ from later API descriptions. These source issues are retained and require checking against actual V2.5.0 SDK headers/API references before execution. Code and parameters remain; PDF wrapping and table continuations are repaired.
RKNN2 SDK V2.5.0 · 3/22
1. Software stack and core concepts
2. Environment, versions and board connection
Development workflow and interface selection
4. Model conversion and ONNX editing
5. Quantization, hybrid quantization and QAT
6. Inference, accuracy, performance and memory evaluation
7. Runtime lifecycle, layouts and memory
8. Zero-copy interfaces and I/O constraints
9. C API deployment and code generation
10. Toolkit Lite2 Python deployment
11. Matmul API and matrix layouts
12. NPU multicore configuration and performance
13. Dynamic-shape models and deployment
16. Cache coherency and sparse inference
17. Custom operators: Python and C API
18. Encrypted model deployment
20. Performance analysis and network optimization
21. Memory analysis, sharing and reuse
22. FAQ, error handling and references
1.3 Development Process and Interface Selection
1.3.1 General Model Development Process
Users can refer to the following flowchart to understand the overall RKNN development steps. The process is mainly divided into 3 parts: model conversion, model evaluation, and on-board deployment and running.
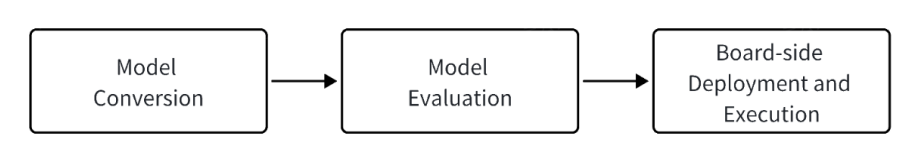
Figure 1-5 RKNN Development Flowchart
1. Model Conversion:
In this stage, the original deep learning model is converted into the RKNN format for efficient inference on RKNPU platforms. This stage includes the following 5 steps:
a. Obtain the original model: Obtain or train a deep learning model. It is recommended to use mainstream frameworks such as ONNX, PyTorch, or TensorFlow.
b. Model configuration: Make the necessary configurations in RKNN-Toolkit2, such as normalization parameters, quantization parameters, and target platform.
c. Model loading: Import the model into RKNN-Toolkit2 using the appropriate loading interface, and select the correct loading interface according to the model framework.
d. Model building: Build the RKNN model with the rknn.build() interface; you can choose whether to perform quantization to improve the model’s inference performance on the hardware.
e. Model export: Export the RKNN model as a file (.rknn format) with the rknn.export_rknn() interface for subsequent deployment.
For details, see section 2.1 General Model Conversion.
2.Model Evaluation:
The main goal of this stage is to evaluate key metrics such as the accuracy of model inference results, inference performance, and memory usage. The main steps of evaluation are as follows:
a. Board-connected model debugging: Use Python to connect to the RKNPU platform to run inference on the model and verify the accuracy of the results. This stage covers pre-processing of the input data and post-processing of the output results, to ensure the model runs correctly on the board.
b. Accuracy evaluation: Use the rknn.accuracy_analysis() interface to compare the differences between the inference results of the quantized model and the floating-point model, in order to analyze the sources of quantization error.
c. Performance evaluation: Use the rknn.eval_perf() interface to analyze the inference performance of the model on the RKNPU platform, helping users further optimize the model structure and speed up inference performance.
d. Memory evaluation: Use the rknn.eval_memory() interface to understand the memory usage of the model on the RKNPU platform, helping users further optimize the model structure and minimize memory usage.
For details, see sections 2.3 Model Evaluation, 3.2 Deploying General Models with the C API, and
3.3 Toolkit Lite Python Deployment.
3. On-board deployment and running:
This stage covers the actual deployment and running of the model. It typically includes the following steps:
a. Model initialization: Load the RKNN model onto the RKNPU platform and prepare for pre- processing.
b. Model pre-processing: Load the data to be inferred onto the RKNPU platform and prepare for inference.
c. Model inference: Perform the inference operation, passing the input data to the model and obtaining the inference results.
d. Model post-processing: Obtain the inference results for post-processing, and pass the post- processed results to the application side.
e. Model release: After completing the inference process, release the model resources so that the RKNN model can be used by other tasks.
For details, see section 3.3 Toolkit Lite Python Deployment.
These three steps constitute the complete RKNN development process, ensuring that artificial intelligence models can be successfully converted, debugged, evaluated, and finally deployed efficiently on the RKNPU.
1.3.2 Interface Selection
The RKNN2 SDK provides two on-board invocation methods; users choose according to the scenario:
| Method | Language | Applicable Scenarios |
|---|---|---|
| RKNN Runtime (C API) | C / C++ | Production deployment, performance-sensitive scenarios |
| RKNN-Toolkit Lite2 (Python API) | Python | Quick on-board verification, prototype development |
Differences between the two:
Performance: The C API delivers the best performance; Toolkit Lite is slightly lower due to the overhead of the Python wrapper.
Development convenience: Toolkit Lite is more convenient (Python programming, no cross-compilation required); the C API requires cross-compilation and integration into the on- board application.
Feature completeness: The C API supports the full set of advanced features (zero-copy, NPU multi-core, matrix multiplication interface, dynamic shape, SRAM, model encryption, etc.); Toolkit Lite targets quick on-board verification and covers fewer advanced features.
Selection suggestions:
Production deployment / performance-sensitive scenarios: Use the C API, which provides optimal performance and complete features, and supports security features such as encrypted model deployment.
On-board verification / prototype development: Use Toolkit Lite; no cross-compilation is needed, and with the converted .rknn model, inference results can be quickly verified on the board.
Note: For detailed usage of the two interfaces, see 3.2 Deploying General Models with the C API and 3.3 Toolkit Lite Python Deployment.
1.3.3 Model Conversion and Deployment Artifacts
The deployment artifacts generated after model conversion are as follows:
| File/Directory | Description |
|---|---|
| .rknn | RKNN model file, containing the model structure and weights |
| C++ deployment example code (optional) | Generated via the cpp_gen_cfg parameter of rknn.export_rknn() or the rknn.codegen() interface; it can be used to test performance and verify accuracy directly, and can also be used for secondary development |
Note: The model exported by RKNN2 is a single .rknn file (model structure and weights integrated in one). During deployment, the .rknn model must be transferred to the board: C API deployment loads it via rknn_init() , and Toolkit Lite2 deployment loads it via init() . For a description of the artifacts in model encryption deployment scenarios, see 4.2.2 Model Encryption Deployment.