
This RKNN2 V2.5.0 platform reference helps ArmSoM developers select and adapt models. It does not establish support on every ArmSoM board: verify the board SoC, actual Toolkit2, Runtime, NPU driver and BSP versions. The source specifies no universal Linux kernel version. No ArmSoM hardware validation was performed.
Source: the supplied Chinese and English RKNN2 Supported Operators and Constraints Reference V2.5.0, 374 and 384 pages respectively. Chinese follows the Chinese edition; English, Russian and German follow the English edition. Platform constraints remain separate. The English PDF itself contains Chinese I/O figures and output tables; their provenance is retained with editable localized tables. Source spellings such as ConvTranpose and the original LSTM/GRU equations are preserved; these equations are not corrections to SDK implementations.
Source pages: CN 368–374; EN 378–384.
Operator reference series
RKNN2 V2.5.0 · RK3566/RK3568:Basics and convolution
RKNN2 V2.5.0 · RK3566/RK3568:Recurrent networks, arithmetic and pooling
RKNN2 V2.5.0 · RK3566/RK3568:Shapes, slicing and transpose
RKNN2 V2.5.0 · RK3566/RK3568:Activations, normalization and extensions
RKNN2 V2.5.0 · RK3588:Basics and convolution
RKNN2 V2.5.0 · RK3588:Recurrent networks, arithmetic and pooling
RKNN2 V2.5.0 · RK3588:Shapes, slicing and transpose
RKNN2 V2.5.0 · RK3588:Activations, normalization and extensions
RKNN2 V2.5.0 · RK3562:Basics and convolution
RKNN2 V2.5.0 · RK3562:Recurrent networks, arithmetic and pooling
RKNN2 V2.5.0 · RK3562:Shapes, slicing and transpose
RKNN2 V2.5.0 · RK3562:Activations, normalization and extensions
RKNN2 V2.5.0 · RV1103/RV1106:Basics and convolution
RKNN2 V2.5.0 · RV1103/RV1106:Recurrent networks, arithmetic and pooling
RKNN2 V2.5.0 · RV1103/RV1106:Shapes, slicing and transpose
RKNN2 V2.5.0 · RV1103/RV1106:Activations, normalization and extensions
RKNN2 V2.5.0 · RK3576/RV1126B:Basics and convolution
RKNN2 V2.5.0 · RK3576/RV1126B:Recurrent networks, arithmetic and pooling
RKNN2 V2.5.0 · RK3576/RV1126B:Shapes, slicing and transpose
RKNN2 V2.5.0 · RK3576/RV1126B:Activations, normalization and extensions
RKNN2 V2.5.0 · RK2118:Basics and convolution
RKNN2 V2.5.0 · RK2118:Recurrent networks, arithmetic and pooling
RKNN2 V2.5.0 · RK2118:Shapes, slicing and transpose
RKNN2 V2.5.0 · RK2118:Activations, normalization and extensions
RKNN2 V2.5.0 · RV1103B/RV1106B:Basics and convolution
RKNN2 V2.5.0 · RV1103B/RV1106B:Recurrent networks, arithmetic and pooling
RKNN2 V2.5.0 · RV1103B/RV1106B:Shapes, slicing and transpose
RKNN2 V2.5.0 · RV1103B/RV1106B:Activations, normalization and extensions
RKNN2 V2.5.0 · CPU operator support and constraints
RKNN2 V2.5.0 · GPU operator support and constraints
RKNN2 V2.5.0 · Model I/O, alignment and convolution limits
Model I/O Limitations
Model Input Limitations
-
The alignment constraints apply only to the zero-copy API; the normal API has no such constraints.
-
The input width alignment requirement can be queried from the w_stride attribute of the zero-copy API. Note: w_stride cannot be changed.
-
Only the input width has alignment requirements under different channel conditions; there are no other constraints.
-
If mean and scale are not needed for the input, set mean to 0 and scale to 1.
-
If channel > 4, mean/scale uniformly use the first value, i.e., mean[0] and scale[0].
-
If the first layer is floating-point type, there is no quant operation.
-
RV1106/RV1103/RV1103B do not support CPU mean/scale/quant operations.
-
For detailed usage, refer to “Rockchip_RKNPU_User_Guide_RKNN_SDK”.
RK3566/RK3568
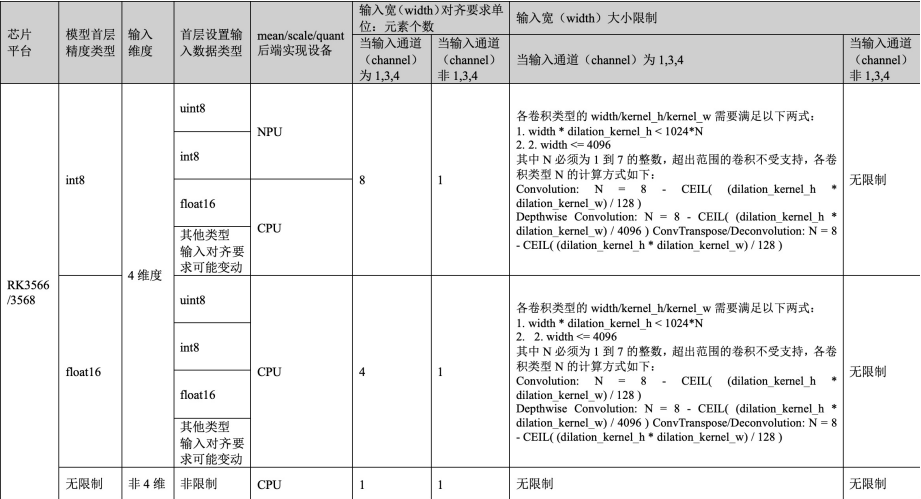
Editable transcription of the original (merged cells expanded):
| Platform | First-layer precision | Input dimensions | Configured first-layer input type | mean/scale/quant backend | width alignment (elements), channel=1,3,4 | width alignment (elements), channel≠1,3,4 | width limits, channel=1,3,4 | width limits, channel≠1,3,4 |
|---|---|---|---|---|---|---|---|---|
| RK3566/RK3568 | int8 | 4 | uint8 | NPU | 8 | 1 | A | Unrestricted |
| RK3566/RK3568 | int8 | 4 | int8 | NPU | 8 | 1 | A | Unrestricted |
| RK3566/RK3568 | int8 | 4 | float16 | CPU | 8 | 1 | A | Unrestricted |
| RK3566/RK3568 | int8 | 4 | Other types (input alignment may change) | CPU | 8 | 1 | A | Unrestricted |
| RK3566/RK3568 | float16 | 4 | uint8 | CPU | 4 | 1 | B | Unrestricted |
| RK3566/RK3568 | float16 | 4 | int8 | CPU | 4 | 1 | B | Unrestricted |
| RK3566/RK3568 | float16 | 4 | float16 | CPU | 4 | 1 | B | Unrestricted |
| RK3566/RK3568 | float16 | 4 | Other types (input alignment may change) | CPU | 4 | 1 | B | Unrestricted |
| RK3566/RK3568 | Unrestricted | Not 4-dimensional | Unrestricted | CPU | 1 | 1 | Unrestricted | Unrestricted |
For each convolution type, width/kernel_h/kernel_w must satisfy both conditions below. N must be an integer from 1 to 7; convolutions outside that range are unsupported. N is computed below. The image spells dilation_kernel_h/w differently from dilated_kernel_h/w in the last chapter; the image spelling is preserved.
| Condition | Formula |
|---|---|
| A (1) | width * dilation_kernel_h < 1024 * N |
| A (2) | width <= 4096 |
| A / Convolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 128) |
| A / Depthwise Convolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 4096) |
| A / ConvTranspose/Deconvolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 128) |
| Condition | Formula |
|---|---|
| B (1) | width * dilation_kernel_h < 1024 * N |
| B (2) | width <= 4096 |
| B / Convolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 128) |
| B / Depthwise Convolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 4096) |
| B / ConvTranspose/Deconvolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 128) |
RK3588
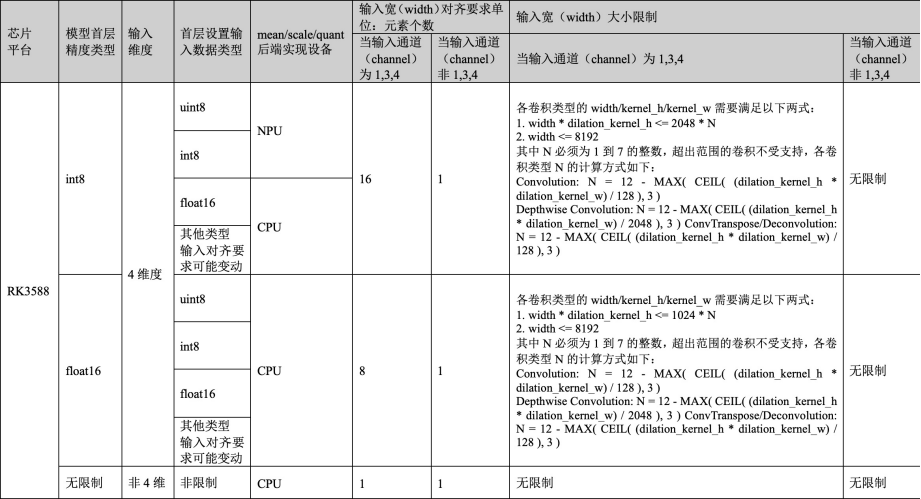
Editable transcription of the original (merged cells expanded):
| Platform | First-layer precision | Input dimensions | Configured first-layer input type | mean/scale/quant backend | width alignment (elements), channel=1,3,4 | width alignment (elements), channel≠1,3,4 | width limits, channel=1,3,4 | width limits, channel≠1,3,4 |
|---|---|---|---|---|---|---|---|---|
| RK3588 | int8 | 4 | uint8 | NPU | 16 | 1 | A | Unrestricted |
| RK3588 | int8 | 4 | int8 | NPU | 16 | 1 | A | Unrestricted |
| RK3588 | int8 | 4 | float16 | CPU | 16 | 1 | A | Unrestricted |
| RK3588 | int8 | 4 | Other types (input alignment may change) | CPU | 16 | 1 | A | Unrestricted |
| RK3588 | float16 | 4 | uint8 | CPU | 8 | 1 | B | Unrestricted |
| RK3588 | float16 | 4 | int8 | CPU | 8 | 1 | B | Unrestricted |
| RK3588 | float16 | 4 | float16 | CPU | 8 | 1 | B | Unrestricted |
| RK3588 | float16 | 4 | Other types (input alignment may change) | CPU | 8 | 1 | B | Unrestricted |
| RK3588 | Unrestricted | Not 4-dimensional | Unrestricted | CPU | 1 | 1 | Unrestricted | Unrestricted |
For each convolution type, width/kernel_h/kernel_w must satisfy both conditions below. N must be an integer from 1 to 7; convolutions outside that range are unsupported. N is computed below. The image spells dilation_kernel_h/w differently from dilated_kernel_h/w in the last chapter; the image spelling is preserved.
| Condition | Formula |
|---|---|
| A (1) | width * dilation_kernel_h <= 2048 * N |
| A (2) | width <= 8192 |
| A / Convolution | N = 12 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 3) |
| A / Depthwise Convolution | N = 12 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 2048), 3) |
| A / ConvTranspose/Deconvolution | N = 12 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 3) |
| Condition | Formula |
|---|---|
| B (1) | width * dilation_kernel_h <= 1024 * N |
| B (2) | width <= 8192 |
| B / Convolution | N = 12 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 3) |
| B / Depthwise Convolution | N = 12 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 2048), 3) |
| B / ConvTranspose/Deconvolution | N = 12 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 3) |
RV1103/RV1106
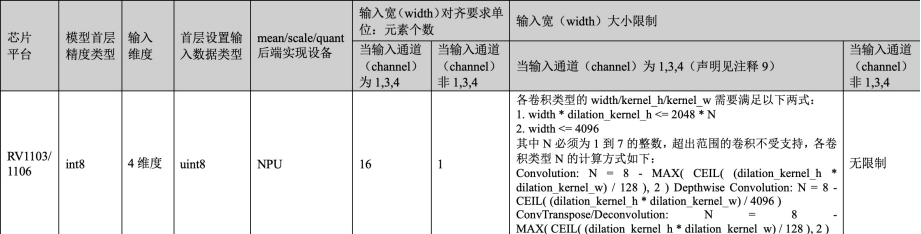
Editable transcription of the original (merged cells expanded):
| Platform | First-layer precision | Input dimensions | Configured first-layer input type | mean/scale/quant backend | width alignment (elements), channel=1,3,4 | width alignment (elements), channel≠1,3,4 | width limits, channel=1,3,4 | width limits, channel≠1,3,4 |
|---|---|---|---|---|---|---|---|---|
| RV1103/RV1106 | int8 | 4 | uint8 | NPU | 16 | 1 | A | Unrestricted |
For each convolution type, width/kernel_h/kernel_w must satisfy both conditions below. N must be an integer from 1 to 7; convolutions outside that range are unsupported. N is computed below. The image spells dilation_kernel_h/w differently from dilated_kernel_h/w in the last chapter; the image spelling is preserved.
| Condition | Formula |
|---|---|
| A (1) | width * dilation_kernel_h <= 2048 * N |
| A (2) | width <= 4096 |
| A / Convolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
| A / Depthwise Convolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 4096) |
| A / ConvTranspose/Deconvolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
The original header refers to note 9, but the supplied input notes list only 1–8. Note 9 was not found and is not invented.
RK3562
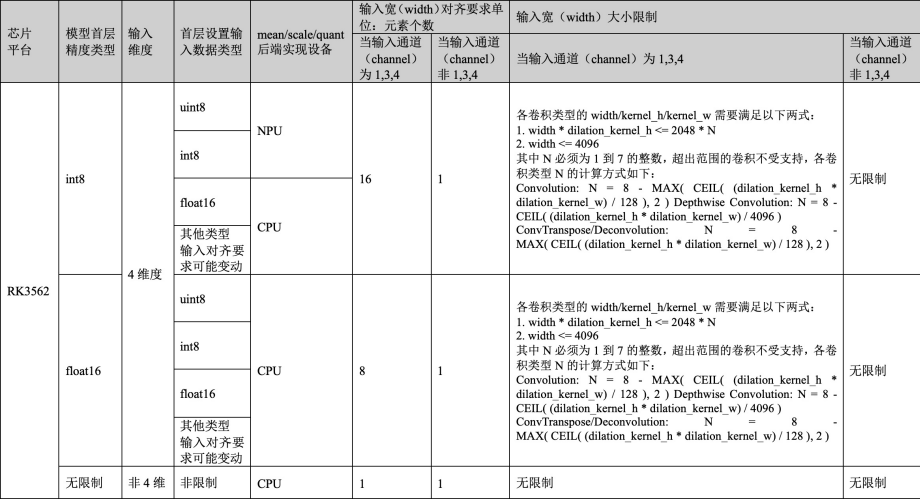
Editable transcription of the original (merged cells expanded):
| Platform | First-layer precision | Input dimensions | Configured first-layer input type | mean/scale/quant backend | width alignment (elements), channel=1,3,4 | width alignment (elements), channel≠1,3,4 | width limits, channel=1,3,4 | width limits, channel≠1,3,4 |
|---|---|---|---|---|---|---|---|---|
| RK3562 | int8 | 4 | uint8 | NPU | 16 | 1 | A | Unrestricted |
| RK3562 | int8 | 4 | int8 | NPU | 16 | 1 | A | Unrestricted |
| RK3562 | int8 | 4 | float16 | CPU | 16 | 1 | A | Unrestricted |
| RK3562 | int8 | 4 | Other types (input alignment may change) | CPU | 16 | 1 | A | Unrestricted |
| RK3562 | float16 | 4 | uint8 | CPU | 8 | 1 | B | Unrestricted |
| RK3562 | float16 | 4 | int8 | CPU | 8 | 1 | B | Unrestricted |
| RK3562 | float16 | 4 | float16 | CPU | 8 | 1 | B | Unrestricted |
| RK3562 | float16 | 4 | Other types (input alignment may change) | CPU | 8 | 1 | B | Unrestricted |
| RK3562 | Unrestricted | Not 4-dimensional | Unrestricted | CPU | 1 | 1 | Unrestricted | Unrestricted |
For each convolution type, width/kernel_h/kernel_w must satisfy both conditions below. N must be an integer from 1 to 7; convolutions outside that range are unsupported. N is computed below. The image spells dilation_kernel_h/w differently from dilated_kernel_h/w in the last chapter; the image spelling is preserved.
| Condition | Formula |
|---|---|
| A (1) | width * dilation_kernel_h <= 2048 * N |
| A (2) | width <= 4096 |
| A / Convolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
| A / Depthwise Convolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 4096) |
| A / ConvTranspose/Deconvolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
| Condition | Formula |
|---|---|
| B (1) | width * dilation_kernel_h <= 2048 * N |
| B (2) | width <= 4096 |
| B / Convolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
| B / Depthwise Convolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 4096) |
| B / ConvTranspose/Deconvolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
RK3576/RV1126B
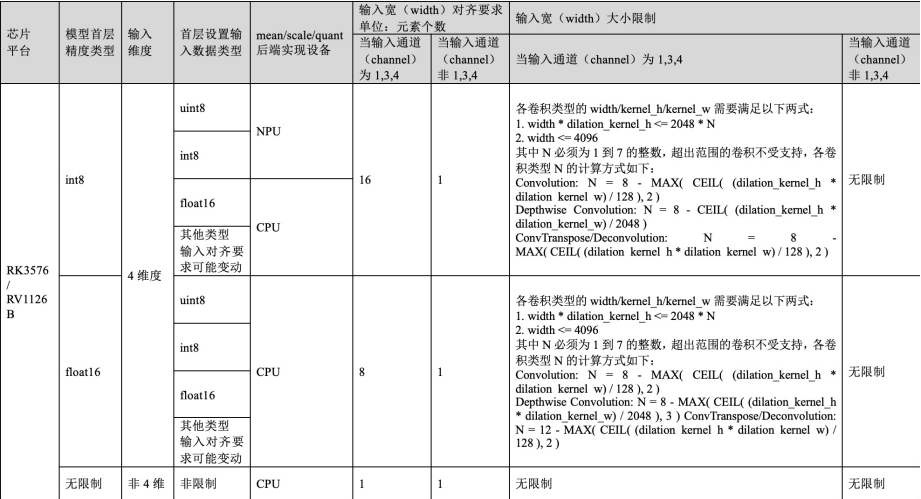
Editable transcription of the original (merged cells expanded):
| Platform | First-layer precision | Input dimensions | Configured first-layer input type | mean/scale/quant backend | width alignment (elements), channel=1,3,4 | width alignment (elements), channel≠1,3,4 | width limits, channel=1,3,4 | width limits, channel≠1,3,4 |
|---|---|---|---|---|---|---|---|---|
| RK3576/RV1126B | int8 | 4 | uint8 | NPU | 16 | 1 | A | Unrestricted |
| RK3576/RV1126B | int8 | 4 | int8 | NPU | 16 | 1 | A | Unrestricted |
| RK3576/RV1126B | int8 | 4 | float16 | CPU | 16 | 1 | A | Unrestricted |
| RK3576/RV1126B | int8 | 4 | Other types (input alignment may change) | CPU | 16 | 1 | A | Unrestricted |
| RK3576/RV1126B | float16 | 4 | uint8 | CPU | 8 | 1 | B | Unrestricted |
| RK3576/RV1126B | float16 | 4 | int8 | CPU | 8 | 1 | B | Unrestricted |
| RK3576/RV1126B | float16 | 4 | float16 | CPU | 8 | 1 | B | Unrestricted |
| RK3576/RV1126B | float16 | 4 | Other types (input alignment may change) | CPU | 8 | 1 | B | Unrestricted |
| RK3576/RV1126B | Unrestricted | Not 4-dimensional | Unrestricted | CPU | 1 | 1 | Unrestricted | Unrestricted |
For each convolution type, width/kernel_h/kernel_w must satisfy both conditions below. N must be an integer from 1 to 7; convolutions outside that range are unsupported. N is computed below. The image spells dilation_kernel_h/w differently from dilated_kernel_h/w in the last chapter; the image spelling is preserved.
| Condition | Formula |
|---|---|
| A (1) | width * dilation_kernel_h <= 2048 * N |
| A (2) | width <= 4096 |
| A / Convolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
| A / Depthwise Convolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 2048) |
| A / ConvTranspose/Deconvolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
| Condition | Formula |
|---|---|
| B (1) | width * dilation_kernel_h <= 2048 * N |
| B (2) | width <= 4096 |
| B / Convolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
| B / Depthwise Convolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 2048), 3) |
| B / ConvTranspose/Deconvolution | N = 12 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
RK2118
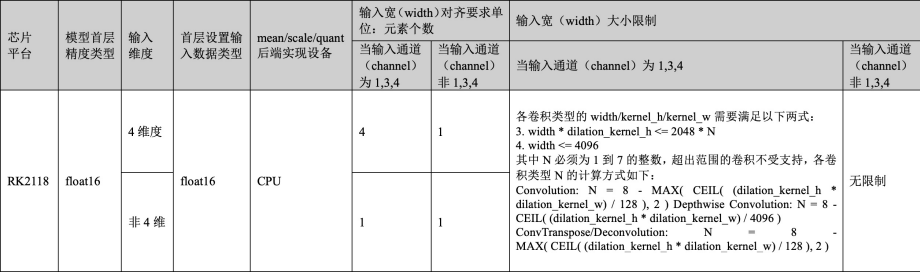
Editable transcription of the original (merged cells expanded):
| Platform | First-layer precision | Input dimensions | Configured first-layer input type | mean/scale/quant backend | width alignment (elements), channel=1,3,4 | width alignment (elements), channel≠1,3,4 | width limits, channel=1,3,4 | width limits, channel≠1,3,4 |
|---|---|---|---|---|---|---|---|---|
| RK2118 | float16 | 4 | float16 | CPU | 4 | 1 | A | Unrestricted |
| RK2118 | float16 | Not 4-dimensional | float16 | CPU | 1 | 1 | A | Unrestricted |
For each convolution type, width/kernel_h/kernel_w must satisfy both conditions below. N must be an integer from 1 to 7; convolutions outside that range are unsupported. N is computed below. The image spells dilation_kernel_h/w differently from dilated_kernel_h/w in the last chapter; the image spelling is preserved.
| Condition | Formula |
|---|---|
| A (1) | width * dilation_kernel_h <= 2048 * N |
| A (2) | width <= 4096 |
| A / Convolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
| A / Depthwise Convolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 4096) |
| A / ConvTranspose/Deconvolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
RV1103B
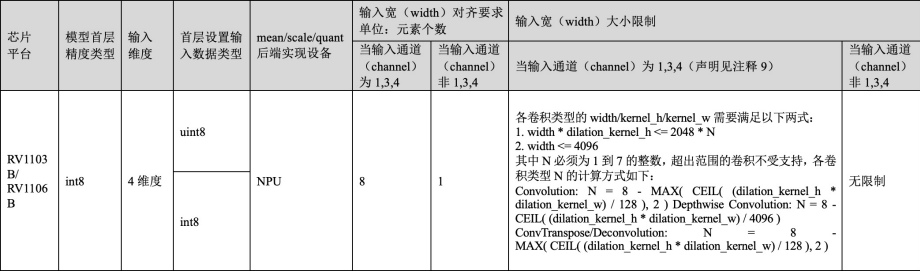
Editable transcription of the original (merged cells expanded):
| Platform | First-layer precision | Input dimensions | Configured first-layer input type | mean/scale/quant backend | width alignment (elements), channel=1,3,4 | width alignment (elements), channel≠1,3,4 | width limits, channel=1,3,4 | width limits, channel≠1,3,4 |
|---|---|---|---|---|---|---|---|---|
| RV1103B/RV1106B | int8 | 4 | uint8 | NPU | 8 | 1 | A | Unrestricted |
| RV1103B/RV1106B | int8 | 4 | int8 | NPU | 8 | 1 | A | Unrestricted |
For each convolution type, width/kernel_h/kernel_w must satisfy both conditions below. N must be an integer from 1 to 7; convolutions outside that range are unsupported. N is computed below. The image spells dilation_kernel_h/w differently from dilated_kernel_h/w in the last chapter; the image spelling is preserved.
| Condition | Formula |
|---|---|
| A (1) | width * dilation_kernel_h <= 2048 * N |
| A (2) | width <= 4096 |
| A / Convolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
| A / Depthwise Convolution | N = 8 - CEIL((dilation_kernel_h * dilation_kernel_w) / 4096) |
| A / ConvTranspose/Deconvolution | N = 8 - MAX(CEIL((dilation_kernel_h * dilation_kernel_w) / 128), 2) |
The original header refers to note 9, but the supplied input notes list only 1–8. Note 9 was not found and is not invented.
Model Output Limitations
-
If the output tensor type is NHWC and the output conversion is implemented by the NPU, there are alignment requirements; CPU implementations have no alignment requirements.
-
The output precision type int8/float16 indicates the data type of the raw output of the last layer of the model.
-
For NCHW output, if implemented by the NPU with the zero-copy interface, the output memory size should be based on the queried size.
-
For NC1HWC2 output, the output memory size should be based on the queried size.
RK3566/RK3568
| Platform | Model output precision | Output dimensions | Output layout | Channel alignment | H*W alignment |
|---|---|---|---|---|---|
| RK3566/RK3568 | int8 | 4 | NCHW | None | None |
| RK3566/RK3568 | int8 | 4 | NHWC | Aligned to 8 | None |
| RK3566/RK3568 | int8 | 4 | NC1HWC2 | Last layer convolution: aligned to 16; non-convolution: aligned to 8 | Aligned to 4 |
| RK3566/RK3568 | int8 | 4 | UNDEFINE | None | None |
| RK3566/RK3568 | float16 | 4 | NCHW | None | None |
| RK3566/RK3568 | float16 | 4 | NHWC | Aligned to 4 | None |
| RK3566/RK3568 | float16 | 4 | NC1HWC2 | Last layer convolution: aligned to 8; non-convolution: aligned to 4 | Aligned to 4 |
| RK3566/RK3568 | float16 | 4 | UNDEFINE | None | None |
| RK3566/RK3568 | Unrestricted | Not 4D | UNDEFINE | None | None |
RK3588
| Platform | Model output precision | Output dimensions | Output layout | Channel alignment | H*W alignment |
|---|---|---|---|---|---|
| RK3588 | int8 | 4 | NCHW | None | None |
| RK3588 | int8 | 4 | NHWC | Aligned to 16 | None |
| RK3588 | int8 | 4 | NC1HWC2 | Last layer convolution: aligned to 32; non-convolution: aligned to 16 | Aligned to 4 |
| RK3588 | int8 | 4 | UNDEFINE | None | None |
| RK3588 | float16 | 4 | NCHW | None | None |
| RK3588 | float16 | 4 | NHWC | Aligned to 8 | None |
| RK3588 | float16 | 4 | NC1HWC2 | Last layer convolution: aligned to 16; non-convolution: aligned to 8 | Aligned to 4 |
| RK3588 | float16 | 4 | UNDEFINE | None | None |
| RK3588 | Unrestricted | Not 4D | UNDEFINE | None | None |
RV1103/RV1106
| Platform | Model output precision | Output dimensions | Output layout | Channel alignment | H*W alignment |
|---|---|---|---|---|---|
| RV1103/RV1106 | int8 | 4 | NC1HWC2 | Last layer convolution: aligned to 32; non-convolution: aligned to 16 | Aligned to 4 |
| RV1103/RV1106 | int8 | 4 | NHWC | None | None |
RK3562
| Platform | Model output precision | Output dimensions | Output layout | Channel alignment | H*W alignment |
|---|---|---|---|---|---|
| RK3562 | int8 | 4 | NCHW | None | None |
| RK3562 | int8 | 4 | NHWC | None | None |
| RK3562 | int8 | 4 | NC1HWC2 | Last layer convolution: aligned to 32; non-convolution: aligned to 16 | Aligned to 4 |
| RK3562 | int8 | 4 | UNDEFINE | None | None |
| RK3562 | float16 | 4 | NCHW | None | None |
| RK3562 | float16 | 4 | NHWC | None | None |
| RK3562 | float16 | 4 | NC1HWC2 | Last layer convolution: aligned to 16; non-convolution: aligned to 8 | Aligned to 4 |
| RK3562 | float16 | 4 | UNDEFINE | None | None |
| RK3562 | Unrestricted | Not 4D | UNDEFINE | None | None |
RK3576/RV1126B
| Platform | Model output precision | Output dimensions | Output layout | Channel alignment | H*W alignment |
|---|---|---|---|---|---|
| RK3576/RV1126B | int8 | 4 | NCHW | None | None |
| RK3576/RV1126B | int8 | 4 | NHWC | None | None |
| RK3576/RV1126B | int8 | 4 | NC1HWC2 | Last layer convolution: aligned to 32; non-convolution: aligned to 16 | Aligned to 4 |
| RK3576/RV1126B | int8 | 4 | UNDEFINE | None | None |
| RK3576/RV1126B | float16 | 4 | NCHW | None | None |
| RK3576/RV1126B | float16 | 4 | NHWC | None | None |
| RK3576/RV1126B | float16 | 4 | NC1HWC2 | Last layer convolution: aligned to 16; non-convolution: aligned to 8 | Aligned to 4 |
| RK3576/RV1126B | float16 | 4 | UNDEFINE | None | None |
| RK3576/RV1126B | Unrestricted | Not 4D | UNDEFINE | None | None |
RK2118
| Platform | Model output precision | Output dimensions | Output layout | Channel alignment | H*W alignment |
|---|---|---|---|---|---|
| RK2118 | float16 | 4 | NC1HWC2 | Last layer convolution: aligned to 8; non-convolution: aligned to 4 | Aligned to 4 |
| RK2118 | float16 | 4 | NHWC | None | None |
| RK2118 | float16 | Not 4D | UNDEFINE | None | None |
RV1103B/RV1106B
| Platform | Model output precision | Output dimensions | Output layout | Channel alignment | H*W alignment |
|---|---|---|---|---|---|
| RV1103B/RV1106B | int8 | 4 | NC1HWC2 | Last layer convolution: aligned to 8; non-convolution: aligned to 8 | Aligned to 4 |
| RV1103B/RV1106B | int8 | 4 | NHWC | None | None |
Special Notes
dilated_kernel_h
dilated_kernel_h = kernel_h * dilations_h - dilations_h + 1
dilated_kernel_w
dilated_kernel_w = kernel_w * dilations_w - dilations_w + 1